Speech recognition
Technology that turns spoken words into written text.
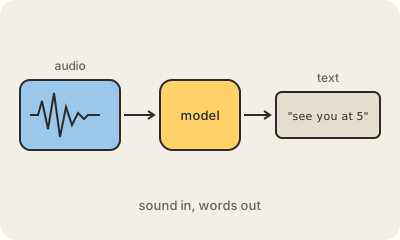
Speech recognition, also called speech-to-text, is what lets a computer listen to someone talk and write down what they said. Your phone's dictation, automatic subtitles on videos, voice assistants and the transcript of a video call all start here.
Older systems were stitched together from separate parts: one to recognize sounds, one to match them to words, one to guess likely sentences. Modern ones are single neural networks trained on hundreds of thousands of hours of recorded speech with their transcripts. OpenAI's Whisper, released as open source in 2022, showed how far that approach goes: one model that handles dozens of languages and noisy audio reasonably well.
It still gets things wrong, especially with strong accents, background noise, people talking over each other, or names and jargon it has never heard. Good services add extras such as telling speakers apart, adding punctuation and accepting a list of custom words. On AWS, the service for this is Amazon Transcribe.
Keep in mind
- Converts audio of people talking into text.
- Behind dictation, subtitles, voice assistants and call transcripts.
- Modern systems are neural networks trained on huge amounts of audio.
- Accents, noise and unusual names are still the hard parts.