Site reliability engineering
Running production systems with software engineering, and a budget for failure.
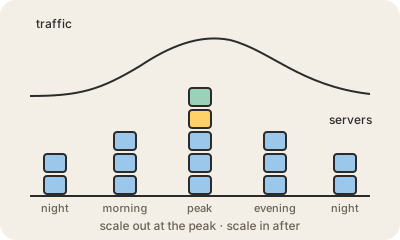
Site reliability engineering, or SRE, is a way of keeping online services reliable by treating operations as a software problem. It began at Google in 2003, when Ben Treynor Sloss was asked to run a production team made of software engineers. Instead of fixing servers by hand, SREs write code that deploys, scales, monitors and repairs systems, and they aim to automate away repetitive manual work, which they call toil.
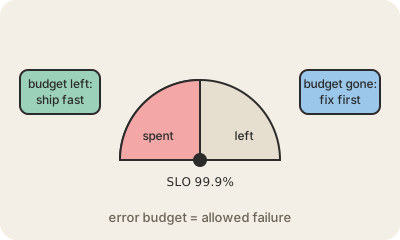
Its best-known idea is the error budget. The team agrees on an SLO, a reliability target such as "99.9% of requests succeed each month". The remaining 0.1% is the budget: room for failures. While there is budget left, developers ship new features fast. If incidents eat it up, releases slow down and effort shifts to reliability. This turns the old fight between "move fast" and "don't break things" into a number both sides accept.
SREs also share on-call duty, lead the response when something breaks, and write blameless postmortems afterward. Many companies now have SRE teams, and the term is also used as a job title. It overlaps a lot with DevOps; one common way to put it is that SRE is a specific, measurable way of doing DevOps.
Keep in mind
- Operations done by engineers who write software to run systems.
- Started at Google in 2003.
- Error budget: the failure allowed by the SLO, spent on moving fast.
- Reduces toil, shares on-call, writes blameless postmortems.
Go deeper
- Introduction to the Site Reliability Engineering book (Google)
- Embracing risk, on error budgets (Google SRE book)
- Site reliability engineering on Wikipedia