Incident postmortem
A written review of what went wrong in an outage and how to avoid a repeat.
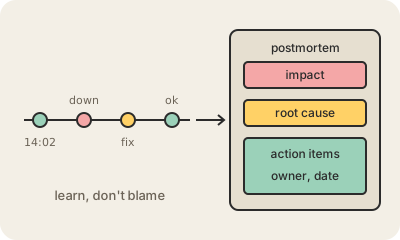
An incident postmortem is the document a team writes after something breaks in production: the site went down, payments failed, data was lost. Once the fire is out, people sit down and reconstruct what happened, minute by minute, so the organization learns from it instead of just moving on.
A typical postmortem has a summary, the impact (who was affected and for how long), a timeline, the root cause and contributing factors, what went well and badly in the response, and a list of action items with owners and dates, such as adding an alert, fixing a script or changing a review process. The action items are the point: a postmortem without follow-up is just a story.
The key cultural rule is that it is blameless. It assumes people acted reasonably with the information they had and asks why the system let a mistake cause damage, not who to punish. If engineers fear blame, they hide details, and the real causes stay buried. Many companies publish postmortems of big outages so customers can see what happened and what changed.
Keep in mind
- Written after an outage: impact, timeline, root cause, action items.
- Blameless: focuses on systems and processes, not on punishing people.
- Action items with owners are what make it worth doing.
- Big companies often publish theirs to keep customers informed.