Temperature
The setting that makes an AI model's answers more predictable or more varied.
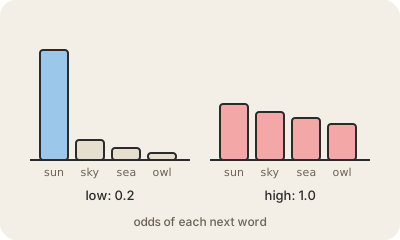
An LLM writes one token at a time, and at every step it has a list of possible next tokens, each with a probability. Temperature is a number you send with your request that changes how the model picks from that list. The name is borrowed from physics, where heat makes particles move more randomly.
At a low temperature, close to 0, the model almost always takes the most likely option. Answers become focused, repetitive and very similar from one run to the next. At a higher temperature the less likely options get a real chance, so the text becomes more varied and surprising, and past a point also more rambling and error-prone. The range depends on the provider: Anthropic's API accepts 0 to 1, OpenAI's 0 to 2.
In practice: keep it low for tasks with one right answer, like pulling data out of an invoice, classifying a message or writing code; raise it for brainstorming, names or fiction where you want options. Even at 0 the output is not guaranteed to be identical every time, and some newer reasoning models fix the temperature and do not let you change it. Temperature is often combined with top-p, which cuts off the long tail of unlikely tokens.
Keep in mind
- Controls how much randomness goes into picking each next token.
- Low means focused and consistent; high means varied and creative.
- Low for extraction, classification and code; higher for ideas.
- Ranges differ by provider, and 0 does not guarantee identical output.
Go deeper
- Messages API reference, temperature parameter (Anthropic)
- Softmax function and temperature on Wikipedia