AI benchmark
A standard test that AI models take so their skills can be compared with a score.
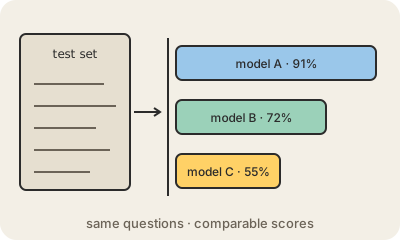
An AI benchmark is a fixed set of tasks with known correct answers that you give to a model to measure how well it does. Every model takes the same test under the same rules, so the scores can be compared. When a company launches a model, the announcement almost always includes a table of benchmark results.
Each benchmark targets a skill. MMLU asks multiple-choice questions across dozens of school and university subjects. GPQA has graduate-level science questions written to be hard to look up. SWE-bench gives the model real bugs from open-source projects and checks whether its fix passes the tests. Others measure math, reading long documents or using a computer. A different style, like LMArena, skips the answer key: people compare two anonymous answers and vote for the better one.
Read the numbers with care. Benchmarks saturate: once top models score near 100%, the test stops telling them apart, and harder ones have to be invented. Test questions can leak into the training data, so a model may have seen the answers. And companies tend to report the tests where they look good. A benchmark score is a useful signal, but the best check is still trying the model on your own tasks.
Keep in mind
- Same questions, same rules, comparable scores across models.
- Each benchmark measures one skill: knowledge, math, coding, tool use.
- Tests saturate and leak into training data, so new ones keep appearing.
- Your own tasks are the benchmark that matters most for you.
Go deeper
- Language model benchmark on Wikipedia
- SWE-bench
- HELM: Holistic Evaluation of Language Models (Stanford)