AI guardrails
Checks placed around an AI model to stop unwanted questions and answers.
AI guardrails are the rules and filters a company puts around a language model so that its app behaves as intended. The model itself is trained to be helpful and avoid harm, but a bank's assistant needs more specific limits: do not give investment advice, do not talk about competitors, never show a full card number, stay polite even when the customer is not.
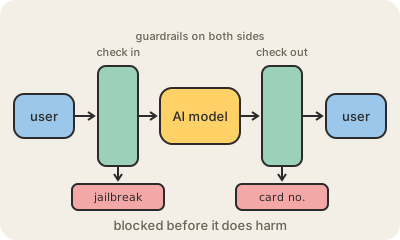
They usually sit on both sides of the model. An input check looks at what the user sends and blocks or rewrites things like jailbreak attempts, prompt injection or off-topic requests. An output check reads the model's answer before the user sees it: it can hide personal data, catch toxic language, refuse forbidden topics or check that the answer is backed by the company's documents, to cut down on hallucinations. Some guardrails are simple rules, like a list of banned words; others are a second, smaller model that judges the first.
Cloud providers sell this as a service, such as Amazon Bedrock Guardrails, and there are open-source tools too. Guardrails are not perfect: too strict and they block reasonable questions, too loose and things slip through. They work best as one layer among several, together with careful prompts, limited permissions and human review where the stakes are high.
Keep in mind
- Input checks filter what reaches the model; output checks filter what reaches the user.
- Typical jobs: block topics, hide personal data, stop jailbreaks, reduce made-up answers.
- They can be simple rules or a second model acting as a judge.
- Too strict annoys users, too loose lets problems through: it takes tuning.
Go deeper
- Amazon Bedrock Guardrails (official docs)
- Mitigate jailbreaks and prompt injections (Claude docs)
- AI Risk Management Framework (NIST)